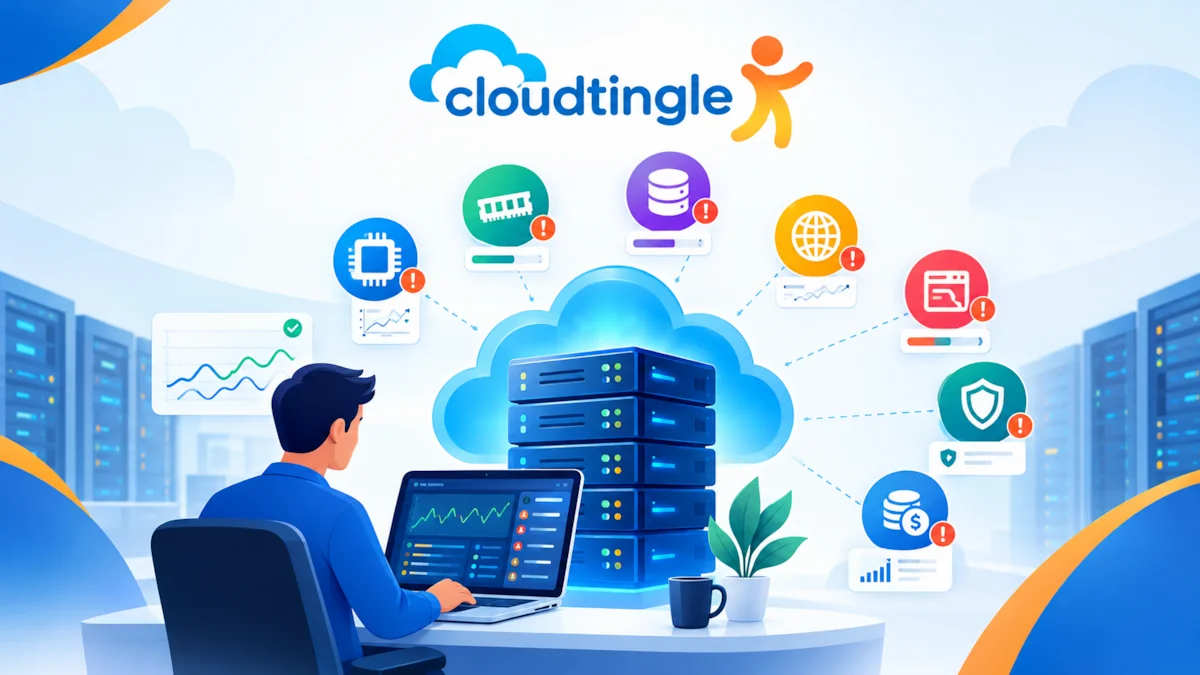
Cloud servers are the backbone of modern digital infrastructure, powering websites, business applications, databases, and mission-critical workloads. Yet, even the most sophisticated infrastructure can experience performance bottlenecks, unexpected outages, security vulnerabilities, or resource exhaustion. The difference between a minor disruption and a costly incident often comes down to one factor: how quickly the problem is detected.
That is where cloud server monitoring becomes indispensable. By configuring the right alerts from the outset, businesses can identify anomalies, resolve emerging issues, and maintain operational continuity without constantly scrutinizing dashboards.
But with dozens of metrics available, where should you begin? The most effective strategy is to prioritise alerts according to their potential impact on availability, performance, security, and cost.
1. CPU Utilisation: Detect Performance Bottlenecks Early
CPU utilisation is one of the most fundamental metrics in server monitoring. When processor usage remains elevated for prolonged periods, applications may become sluggish, background tasks can accumulate, and response times may deteriorate.
Configure an alert when CPU utilisation exceeds 80% for five to ten minutes. A more urgent notification can be triggered if usage surpasses 95% for a sustained interval. These thresholds should be adjusted to reflect workload behaviour, since some computationally intensive applications routinely operate at higher utilisation.
The key is to distinguish between a temporary surge and persistent saturation. A short-lived spike during a scheduled task may be entirely normal; sustained pressure, however, warrants investigation.
2. Memory Usage: Prevent Unresponsive Applications
Memory exhaustion can be deceptively disruptive. Unlike a straightforward CPU spike, insufficient memory may trigger swapping, application instability, or out-of-memory termination.
Configure alerts when memory utilisation exceeds 80–85%, and consider a critical notification above 90%. Where possible, monitor available memory, swap activity, and operating-system out-of-memory events together.
This layered approach provides a clearer picture of server health. A machine approaching its memory limit while swap activity climbs is far more concerning than one experiencing an isolated increase in memory consumption.
For organisations using cloud hosting, proactive memory alerts can help maintain application responsiveness and reduce the likelihood of unplanned service interruptions.
3. Disk Space: Avoid The Consequences Of Storage Exhaustion
Storage depletion is a common but frequently underestimated operational hazard. When a disk fills completely, applications may fail to write logs, databases can encounter errors, and critical system processes may become unstable.
A practical configuration includes a warning at 75–80% disk utilisation and a critical alert at 90%. For smaller system partitions or rapidly growing databases, lower thresholds may be appropriate.
Monitoring free disk space alone is not always sufficient. Track inode availability on Linux systems, disk latency, and input/output operations per second (IOPS) where relevant. A disk with available capacity can still become a performance bottleneck if storage operations are excessively slow.
Early warnings provide valuable time to rotate logs, archive obsolete files, expand storage, or investigate an unexpected increase in data consumption.
4. Network Traffic And Connectivity: Identify Hidden Disruptions
Network health directly influences how users experience an application. Packet loss, elevated latency, bandwidth saturation, and failed connectivity can all undermine performance, even when CPU and memory metrics appear normal.
Configure alerts for sustained increases in network latency, abnormal packet loss, and bandwidth approaching the limits of the server or network interface. Monitor inbound and outbound traffic patterns to identify unusual deviations from established baselines.
Connectivity checks are equally important. An application may be running internally while remaining inaccessible to external users because of a firewall rule, routing issue, DNS failure, or load balancer misconfiguration.
Synthetic monitoring, which periodically tests a website or API from an external vantage point, can help uncover these problems before customers report them.
5. Application Availability And Response Time: Prioritise User Experience
Infrastructure metrics describe the condition of a server, but they do not necessarily reveal whether the service itself is functioning correctly. A server can report healthy CPU and memory levels while its application returns errors or takes several seconds to respond.
Configure availability checks for critical endpoints, with alerts for repeated failed requests or HTTP 5xx errors. Establish response-time thresholds based on the application’s normal performance and user expectations.
For example, an online store may require more stringent latency monitoring during checkout than for a non-essential informational page.
Track error rates, request volume, and service-level indicators alongside response time. This combination helps distinguish genuine service degradation from isolated errors or expected traffic fluctuations.
6. Security Alerts: Detect Suspicious Activity Promptly
Performance matters, but it should never eclipse security. Effective monitoring must help identify suspicious behaviour before it escalates into a significant incident.
Prioritise alerts for repeated failed login attempts, unexpected privilege escalation, unauthorised configuration changes, unusual outbound traffic, and newly exposed services. Where available, integrate operating-system audit logs, identity and access management events, firewall logs, and intrusion detection signals.
For businesses adopting secure cloud hosting, these alerts complement preventive safeguards such as multi-factor authentication, least-privilege access, encryption, and regular patching. Monitoring does not replace these controls; it provides visibility into activity that may evade them.
Security alerts should be routed promptly to the responsible team, with clear escalation procedures for events that could indicate account compromise or data exfiltration.
7. Cost and Resource Alerts: Keep Cloud Spending Predictable
Cloud infrastructure is elastic, but elasticity can introduce financial surprises. Idle instances, oversized resources, unbounded autoscaling, and unexpected data transfers can steadily inflate monthly expenditure.
Set budget notifications at approximately 70%, 85%, and 100% of the planned spending limit. Where supported, configure alerts for abrupt changes in resource consumption and unexpected increases in storage or network charges.
These notifications are particularly valuable when multiple teams deploy workloads independently. Early visibility enables corrective action before a billing anomaly becomes an expensive operational problem.
Businesses evaluating Cloud Hosting Solutions should look beyond headline prices and consider the provider’s monitoring capabilities, billing transparency, and support for resource optimisation.
8. Build An Alerting Strategy That Avoids Alert Fatigue
More alerts do not automatically create better monitoring. Excessive notifications can overwhelm teams, conceal urgent incidents, and encourage engineers to ignore warnings altogether.
Begin with alerts tied to customer impact, infrastructure saturation, security threats, and rapidly escalating costs. Define severity levels, establish notification routes, and use sustained thresholds or anomaly detection to minimise noise.
Whenever possible, alerts should include context: the affected resource, the breached threshold, the duration of the problem, and recommended diagnostic steps. Review alert performance periodically, removing redundant notifications and refining thresholds as workloads evolve.
For businesses seeking cloud hosting in India, monitoring policies should also reflect application demand patterns, regional traffic fluctuations, data protection requirements, and the availability of local technical support.
Conclusion
An effective cloud monitoring strategy starts with a handful of carefully selected alerts, not an exhaustive catalogue of every available metric. CPU, memory, disk capacity, network connectivity, application availability, security events, and cloud expenditure provide a strong foundation.
Once these essentials are in place, teams can refine thresholds, introduce predictive monitoring, and automate appropriate responses. The ultimate objective is not merely to detect failure. It is to recognise warning signs early enough to prevent disruption, protect users, and keep cloud infrastructure dependable as business demands grow.